
json-schema-for-llms: let a model read JSON larger than its context window
json-schema-for-llms turns JSON of hundreds of thousands of tokens into a schema of a few hundred that a model can read, and lets the mapping it writes be reused on any document with the same structure.
A model can write a parser or JSONPath for a JSON document if it can see the document’s structure, and many documents are too large to paste into a prompt. We have released the tool we use to give a model that structure as json-schema-for-llms, under the MIT licence.
936,288 tokens of JSON become a 541-token schema
Many API responses run to hundreds of thousands of tokens, more than a context window holds. The library reads every value in the document and writes a JSON Schema that keeps the field names, the types, how often each field appears, value ranges, the full list of values for short categories, and a few real records. The model reads that schema, a few hundred tokens, and writes the parser, and the parser then runs on the full document.
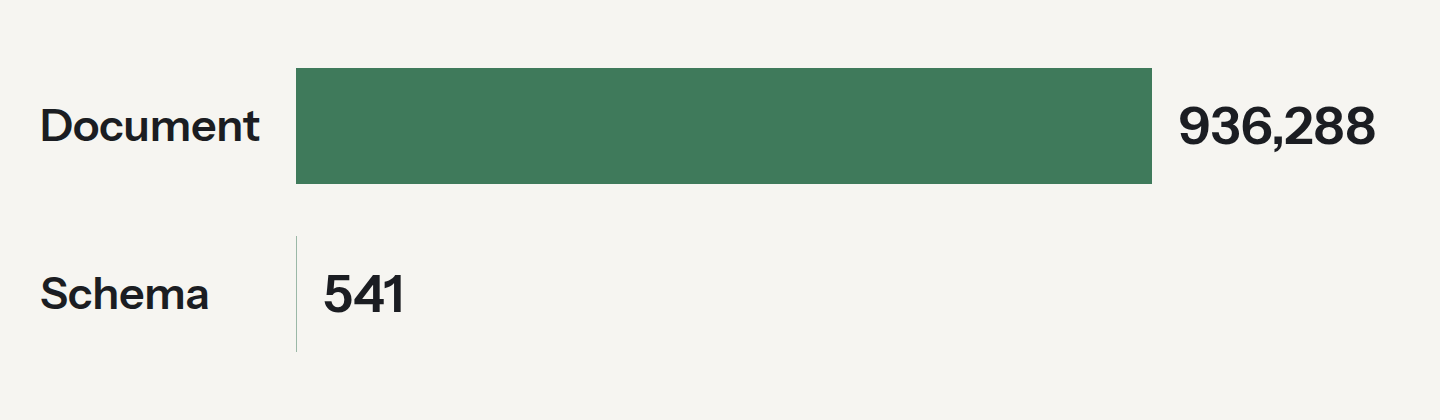
Tokens in a test file of 20,000 orders and in the schema the library writes from it, counted with the o200k tokenizer (GPT-4o and later). Both bars use the same linear scale; the schema has about 1,730 times fewer tokens, so its bar is less than a pixel wide. Source: the library’s test suite.
A mapping written once is reused on documents with the same structure
Two schemas merge into one, so a single schema can cover every document a mapping has handled. For any other document, fits compares its schema with that one and lists the field paths it adds, with no model call. An empty list means the mapping applies, and its output still needs its own checks. A new path is the signal to ask the model for a new mapping, so no field goes unread.
Install from npm
npm install json-schema-for-llms
It runs on Node 18 and later, Bun and Deno, and has no dependencies. The README lists the four functions and what each schema field means. Questions and bug reports go to the repository’s issues, or to queries@carmenaresearch.com.
Sources
Token counts from the library’s test suite (the “README figures” test), counted with the o200k tokenizer.
Methods: how we source, label and check data.
Get new posts by email. One post per email, with its chart and source.
Subscribe